All Models and Download Links for This Software
To keep the software package lightweight, no AI models are pre-installed. Models will be downloaded automatically the first time you use them, mainly from the global repository huggingface.co, mirror sites like hf-mirror.com, and Alibaba ModelScope (modelscope.cn).
This page lists the download links for all supported models and their required local storage locations. If automatic downloads keep failing, you can delete any partially downloaded files and download them manually.
Notes on Model Downloads:
- Models are generally large in size. Accessing overseas repositories directly may require a stable network/proxy connection. When unavailable, the software will automatically attempt to switch to mirror sites.
- Even with a proxy, downloads might still fail if the connection is unstable.
- Mirror sites often enforce rate limits, and their download speeds can fluctuate.
- Due to these reasons, download failures are quite common, and many unexpected errors are indirectly caused by incomplete model downloads.
"Software Directory" refers to the folder where sp.exe or sp.py is located.
- Global Model Hub: https://huggingface.co
- Alibaba Models & ONNX Hub: https://modelscope.cn
Important Download Tips
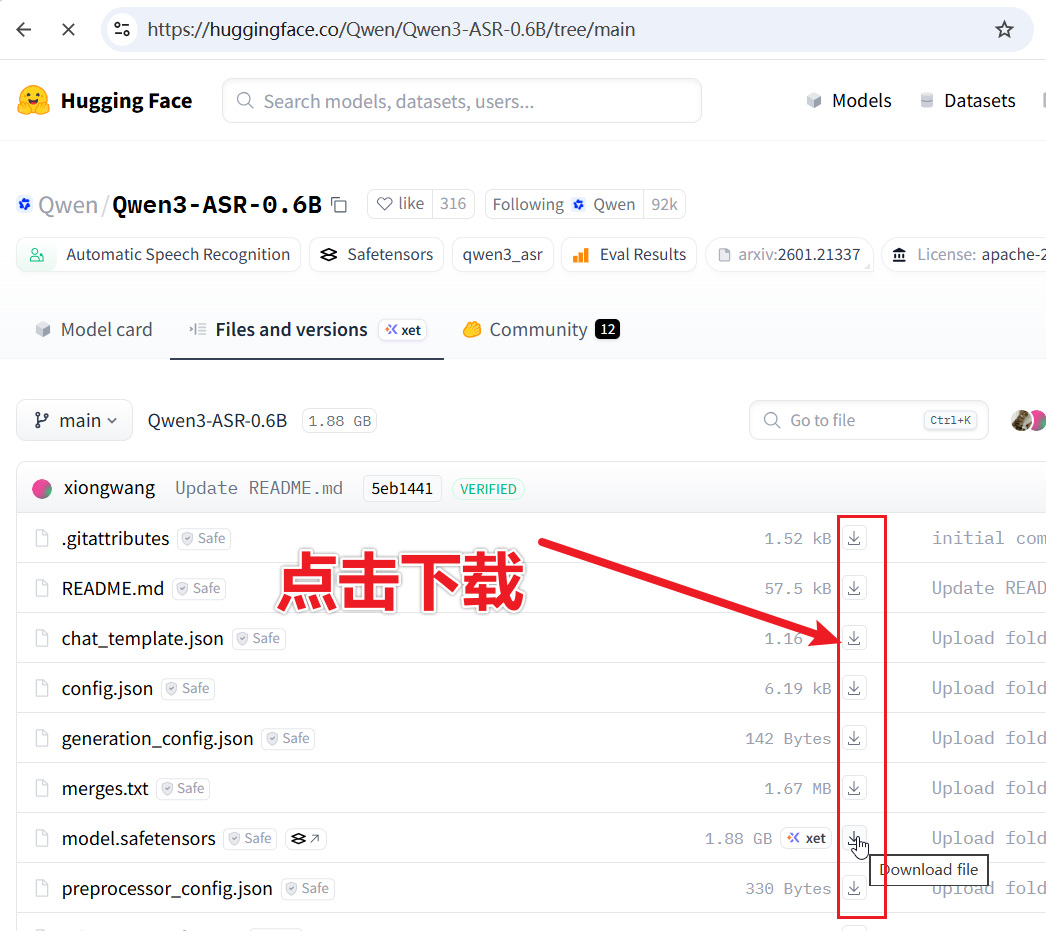
A model usually consists of multiple files, and different models may share identical file names (for example, many include model.safetensors). If a file with the same name already exists in your browser's download folder, your browser may automatically rename it (e.g., model.safetensors becomes model(2).safetensors). You must rename it back to its original name before moving it to the specified folder; otherwise, the software will not recognize it.
On huggingface.co, click the download icon next to each file to download it:
Speech Recognition (ASR) Models
Qwen-ASR (Built-in)
0.6B Model:
- Download link: https://huggingface.co/Qwen/Qwen3-ASR-0.6B/tree/main
- Storage location:
Software Directory/models/models--Qwen--Qwen3-ASR-0.6B
1.7B Model:
- Download link: https://huggingface.co/Qwen/Qwen3-ASR-1.7B/tree/main
- Storage location:
Software Directory/models/models--Qwen--Qwen3-ASR-1.7B
CN-Dialect(Chinese Dialect):
- Download link:https://huggingface.co/ASLP-lab/CN-MultiDialect-ASR/tree/main
- Storage location:
Software Directory/models/models--ASLP-lab--CN-MultiDialect-ASR
Firered Chinese (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/fireredasr2aed.zip
- Storage location:
Software Directory/models/(Extract and copy thefireredasrfolder here)
Dolphin (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/dolphin.zip
- Storage location:
Software Directory/models/(Extract and copy thedolphinfolder here)
Omnilingual Asian Languages (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/omnilingual.zip
- Storage location:
Software Directory/models/(Extract and copy theomnilingualfolder here)
parakeet Japanese (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/parakeet-ja.zip
- Storage location:
Software Directory/models/(Extract and copy theparakeetfolder here)
Moss-Diarize (Built-in)
- Download link: https://huggingface.co/OpenMOSS-Team/MOSS-Transcribe-Diarize/tree/main
- Storage location:
Software Directory/models/models--OpenMOSS-Team--MOSS-Transcribe-Diarize
faster-whisper (Built-in)
| Model Name | Local Storage Location | Download Link |
|---|---|---|
| tiny | Software Directory/models/models--Systran--faster-whisper-tiny | https://huggingface.co/Systran/faster-whisper-tiny/tree/main |
| base | Software Directory/models/models--Systran--faster-whisper-base | https://huggingface.co/Systran/faster-whisper-base/tree/main |
| small | Software Directory/models/models--Systran--faster-whisper-small | https://huggingface.co/Systran/faster-whisper-small/tree/main |
| medium | Software Directory/models/models--Systran--faster-whisper-medium | https://huggingface.co/Systran/faster-whisper-medium/tree/main |
| large-v1 | Software Directory/models/models--Systran--faster-whisper-large-v1 | https://huggingface.co/Systran/faster-whisper-large-v1/tree/main |
| large-v2 | Software Directory/models/models--Systran--faster-whisper-large-v2 | https://huggingface.co/Systran/faster-whisper-large-v2/tree/main |
| large-v3 | Software Directory/models/models--Systran--faster-whisper-large-v3 | https://huggingface.co/Systran/faster-whisper-large-v3/tree/main |
| large-v3-turbo | Software Directory/models/models--mobiuslabsgmbh--faster-whisper-large-v3-turbo | https://huggingface.co/mobiuslabsgmbh/faster-whisper-large-v3-turbo/tree/main |
| --- | --- | --- |
| tiny.en | Software Directory/models/models--Systran--faster-whisper-tiny.en | https://huggingface.co/Systran/faster-whisper-tiny.en/tree/main |
| base.en | Software Directory/models/models--Systran--faster-whisper-base.en | https://huggingface.co/Systran/faster-whisper-base.en/tree/main |
| small.en | Software Directory/models/models--Systran--faster-whisper-small.en | https://huggingface.co/Systran/faster-whisper-small.en/tree/main |
| medium.en | Software Directory/models/models--Systran--faster-whisper-medium.en | https://huggingface.co/Systran/faster-whisper-medium.en/tree/main |
| --- | --- | --- |
| distil-large-v2 | Software Directory/models/models--Systran--faster-distil-whisper-large-v2 | https://huggingface.co/Systran/faster-distil-whisper-large-v2/tree/main |
| distil-large-v3 | Software Directory/models/models--Systran--faster-distil-whisper-large-v3 | https://huggingface.co/Systran/faster-distil-whisper-large-v3/tree/main |
| distil-large-v3.5 | Software Directory/models/models--distil-whisper--distil-large-v3.5-ct2 | https://huggingface.co/distil-whisper/distil-large-v3.5-ct2/tree/main |
| distil-small.en | Software Directory/models/models--Systran--faster-distil-whisper-small.en | https://huggingface.co/Systran/faster-distil-whisper-small.en/tree/main |
| distil-medium.en | Software Directory/models/models--Systran--faster-distil-whisper-medium.en | https://huggingface.co/Systran/faster-distil-whisper-medium.en/tree/main |
openai-whisper (Built-in)
Place downloaded
.ptmodel files directly into theSoftware Directory/modelsfolder.
- tiny.en https://openaipublic.azureedge.net/main/whisper/models/d3dd57d32accea0b295c96e26691aa14d8822fac7d9d27d5dc00b4ca2826dd03/tiny.en.pt
- tiny https://openaipublic.azureedge.net/main/whisper/models/65147644a518d12f04e32d6f3b26facc3f8dd46e5390956a9424a650c0ce22b9/tiny.pt
- base.en https://openaipublic.azureedge.net/main/whisper/models/25a8566e1d0c1e2231d1c762132cd20e0f96a85d16145c3a00adf5d1ac670ead/base.en.pt
- base https://openaipublic.azureedge.net/main/whisper/models/ed3a0b6b1c0edf879ad9b11b1af5a0e6ab5db9205f891f668f8b0e6c6326e34e/base.pt
- small.en https://openaipublic.azureedge.net/main/whisper/models/f953ad0fd29cacd07d5a9eda5624af0f6bcf2258be67c92b79389873d91e0872/small.en.pt
- small https://openaipublic.azureedge.net/main/whisper/models/9ecf779972d90ba49c06d968637d720dd632c55bbf19d441fb42bf17a411e794/small.pt
- medium.en https://openaipublic.azureedge.net/main/whisper/models/d7440d1dc186f76616474e0ff0b3b6b879abc9d1a4926b7adfa41db2d497ab4f/medium.en.pt
- medium https://openaipublic.azureedge.net/main/whisper/models/345ae4da62f9b3d59415adc60127b97c714f32e89e936602e85993674d08dcb1/medium.pt
- large-v1 https://openaipublic.azureedge.net/main/whisper/models/e4b87e7e0bf463eb8e6956e646f1e277e901512310def2c24bf0e11bd3c28e9a/large-v1.pt
- large-v2 https://openaipublic.azureedge.net/main/whisper/models/81f7c96c852ee8fc832187b0132e569d6c3065a3252ed18e56effd0b6a73e524/large-v2.pt
- large-v3 https://openaipublic.azureedge.net/main/whisper/models/e5b1a55b89c1367dacf97e3e19bfd829a01529dbfdeefa8caeb59b3f1b81dadb/large-v3.pt
- large https://openaipublic.azureedge.net/main/whisper/models/e5b1a55b89c1367dacf97e3e19bfd829a01529dbfdeefa8caeb59b3f1b81dadb/large-v3.pt
- large-v3-turbo https://openaipublic.azureedge.net/main/whisper/models/aff26ae408abcba5fbf8813c21e62b0941638c5f6eebfb145be0c9839262a19a/large-v3-turbo.pt
- turbo https://openaipublic.azureedge.net/main/whisper/models/aff26ae408abcba5fbf8813c21e62b0941638c5f6eebfb145be0c9839262a19a/large-v3-turbo.pt
HuggingFace_ASR (Built-in)
Audio8/ARK-ASR-0.6B
- Download link: https://huggingface.co/Audio8/ARK-ASR-0.6B/tree/main
- Storage location:
Software Directory/models/models--Audio8--ARK-ASR-0.6B
Audio8/ARK-ASR-3B
- Download link: https://huggingface.co/Audio8/ARK-ASR-3B/tree/main
- Storage location:
Software Directory/models/models--Audio8--ARK-ASR-3B
ibm-granite/granite-speech-4.1-2b
- Download link: https://huggingface.co/ibm-granite/granite-speech-4.1-2b/tree/main
- Storage location:
Software Directory/models/models--ibm-granite--granite-speech-4.1-2b
zai-org/GLM-ASR-Nano-2512
- Download link: https://huggingface.co/zai-org/GLM-ASR-Nano-2512/tree/main
- Storage location:
Software Directory/models/models--zai-org--GLM-ASR-Nano-2512
anke01/whisper-small-uyghur
- Download link: https://huggingface.co/anke01/whisper-small-uyghur/tree/main
- Storage location:
Software Directory/models/models--anke01--whisper-small-uyghur
nvidia/parakeet-ctc-1.1b (English)
- Download link: https://huggingface.co/nvidia/parakeet-ctc-1.1b/tree/main
- Storage location:
Software Directory/models/models--nvidia--parakeet-ctc-1.1b
reazon-research/japanese-wav2vec2-large-rs35kh (Japanese)
- Download link: https://huggingface.co/reazon-research/japanese-wav2vec2-large-rs35kh/tree/main
- Storage location:
Software Directory/models/models--reazon-research--japanese-wav2vec2-large-rs35kh
kotoba-tech/kotoba-whisper-v2.0 (Japanese)
- Download link: https://huggingface.co/kotoba-tech/kotoba-whisper-v2.0/tree/main
- Storage location:
Software Directory/models/models--kotoba-tech--kotoba-whisper-v2.0
biodatlab/whisper-th-large-v3 (Thai)
- Download link: https://huggingface.co/biodatlab/whisper-th-large-v3/tree/main
- Storage location:
Software Directory/models/models--biodatlab--whisper-th-large-v3
vinai/Phowhisper-large (Vietnamese)
- Download link: https://huggingface.co/vinai/Phowhisper-large/tree/main
- Storage location:
Software Directory/models/models--vinai--Phowhisper-large
openai/whisper-large-v3
- Download link: https://huggingface.co/openai/whisper-large-v3/tree/main
- Storage location:
Software Directory/models/models--openai--whisper-large-v3
whisper.cpp
- Windows precompiled package: After downloading, copy the extracted
whisper-clifolder directly into theSoftware Directory. - Model download links:
Single-file models: Place the downloaded
.binfile into theSoftware Directory/modelsfolder.
Subtitle Translation Models
Hy-MT2-1.8B (Built-in)
- Download link: https://huggingface.co/tencent/Hy-MT2-1.8B/tree/main
- Storage location:
Software Directory/models/models--tencent--Hy-MT2-1.8B
M2M100 (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/m2m100_12b_model.zip
- Storage location:
Software Directory/models/(Extract and copy them2m100_12bfolder here)
Dubbing & Text-to-Speech (TTS) Models
Piper (Built-in)
- Download link: https://huggingface.co/rhasspy/piper-voices/tree/main
- Storage location:
Software Directory/models/piper
VITS (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/vits-tts.zip
- Storage location:
Software Directory/models/(Extract and copy thevitsfolder here)
ZipVoice (Built-in)
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/zipvoice-tts.zip
- Storage location:
Software Directory/models/(Extract and copy thezipvoicefolder here)
OmniVoice (Built-in)
- Download link: https://huggingface.co/k2-fsa/OmniVoice/tree/main
- Storage location:
Software Directory/models/models--k2-fsa--OmniVoice
MOSS-TTS-Nano (Built-in)
- Download link: https://huggingface.co/OpenMOSS-Team/MOSS-TTS-Nano-100M/tree/main
- Storage location:
Software Directory/models/MOSS-TTS-Nano-100M - Download link: https://huggingface.co/OpenMOSS-Team/MOSS-Audio-Tokenizer-Nano-ONNX/tree/main
- Storage location:
Software Directory/models/MOSS-Audio-Tokenizer-Nano-ONNX
ChatterBox (Built-in)
- Download link: https://huggingface.co/ResembleAI/chatterbox/tree/main
- Storage location:
Software Directory/models/models--ResembleAI--chatterbox
Supertonic (Built-in)
- Download link: https://huggingface.co/Supertone/supertonic-3/tree/main
- Storage location:
Software Directory/models/models--Supertone--supertonic-3
Higgs-audio-v3 (Built-in)
- Download link: https://huggingface.co/multimodalart/higgs-audio-v3-tts-4b-transformers/tree/main
- Storage location:
Software Directory/models/models--multimodalart--higgs-audio-v3-tts-4b-transformers
Qwen3-TTS (Built-in)
Download link: https://huggingface.co/Qwen/Qwen3-TTS-12Hz-0.6B-Base/tree/main
Storage location:
Software Directory/models/models--Qwen--Qwen3-TTS-12Hz-0.6B-BaseDownload link: https://huggingface.co/Qwen/Qwen3-TTS-12Hz-0.6B-CustomVoice/tree/main
Storage location:
Software Directory/models/models--Qwen--Qwen3-TTS-12Hz-0.6B-CustomVoice
Confucius-TTS (Built-in)
Download link: https://huggingface.co/netease-youdao/Confucius4-TTS/tree/main
Storage location:
Software Directory/models/models--netease-youdao--Confucius4-TTSDownload link: https://huggingface.co/facebook/w2v-bert-2.0/tree/main
Storage location:
Software Directory/models/models--models--facebook--w2v-bert-2.0Download link: https://huggingface.co/nvidia/bigvgan_v2_22khz_80band_256x/tree/main
Storage location:
Software Directory/models/models--nvidia--bigvgan_v2_22khz_80band_256xDownload link: https://huggingface.co/funasr/campplus/tree/main
Storage location:
Software Directory/models/models--funasr--campplus
F5-TTS (Built-in)
- Official Chinese/English Model (1.35G): https://huggingface.co/SWivid/F5-TTS/tree/main/F5TTS_v1_Base
Storage location:
Software Directory/models/models--SWivid--F5-TTS/F5TTS_v1_Base
- Japanese Model (5.6G): https://huggingface.co/Jmica/F5TTS/tree/main/JA_21999120
Storage location:
Software Directory/models/models--Jmica--F5TTS/JA_21999120
- French Model (5.4G): https://huggingface.co/RASPIAUDIO/F5-French-MixedSpeakers-reduced/tree/main
Storage location:
Software Directory/models/models--RASPIAUDIO--F5-French-MixedSpeakers-reduced
- German Model (1.35G): https://huggingface.co/hvoss-techfak/F5-TTS-German/tree/main
Storage location:
Software Directory/models/models--hvoss-techfak--F5-TTS-German
- Russian Model (3.4G): https://huggingface.co/hotstone228/F5-TTS-Russian/tree/main
Storage location:
Software Directory/models/models--hotstone228--F5-TTS-Russian
- Italian Model (1.35G): https://huggingface.co/alien79/F5-TTS-italian/tree/main
Storage location:
Software Directory/models/models--alien79--F5-TTS-italian
- Spanish Model (5.4G): https://huggingface.co/jpgallegoar/F5-Spanish/tree/main
Storage location:
Software Directory/models/models--jpgallegoar--F5-Spanish
- Hindi Model (2.5G): https://huggingface.co/SPRINGLab/F5-Hindi-24KHz/tree/main
Storage location:
Software Directory/models/models--SPRINGLab/F5-Hindi-24KHz
- Arabic Model (2.6G): https://huggingface.co/silma-ai/silma-tts/tree/main
Storage location:
Software Directory/models/models--silma-ai--silma-tts
- Turkish Model (5.6G): https://huggingface.co/multilingual-tts/F5-TTS-OpenBible-Turkish/tree/main
Storage location:
Software Directory/models/models--multilingual-tts--F5-TTS-OpenBible-Turkish
- Vietnamese Model (5.6G): https://huggingface.co/multilingual-tts/F5-TTS-OpenBible-Vietnamese/tree/main
Storage location:
Software Directory/models/models--multilingual-tts--F5-TTS-OpenBible-Vietnamese
Speaker Diarization Models
Built-in Models:
On this page, download the following 3 files: 3dspeaker_speech_eres2net_large_sv_zh-cn_3dspeaker_16k.onnx, nemo_en_titanet_small.onnx, and seg_model.onnx.
- Storage location: Place the 3 downloaded files into
Software Directory/models/onnx/
pyannote
- Download link: https://huggingface.co/pyannote/speaker-diarization-3.1
- Storage location:
Software Directory/models/models--pyannote--speaker-diarization-3.1
Ali camp++:
- Download link: https://modelscope.cn/models/iic/speech_campplus_speaker-diarization_common
- Storage location:
Software Directory/models/speech_campplus_speaker-diarization_common
Vocal Separation, Noise Reduction, and Punctuation Restoration Models
- Download link: https://modelscope.cn/models/himyworld/videotrans/tree/master/onnx
- Storage location: Download all
.onnxfiles from this page and place them into theSoftware Directory/models/onnx/folder.
Real-time Speech Recognition Models
- Download link: https://modelscope.cn/models/himyworld/videotrans/resolve/master/realtimestt.zip
- Storage location: Extract the downloaded zip file to find an
onnxfolder. Copy all files inside it intoSoftware Directory/models/onnx/.