Recommended Best Settings for Video Translation
This article recommends the best configuration options for each of the four processing stages.
Step 1: Speech Recognition
Goal: Convert the speech in the video into a subtitle file in the corresponding language. The quality of this step directly determines the quality of subsequent subtitle translation and dubbing.
Non-Chinese Videos
| Configuration Level | Channel | Model | Notes |
|---|---|---|---|
| Free (Recommended) | faster-whisper (Built-in) | large-v3 | Balanced speed and quality |
| Free (Alternative) | openai-whisper (Built-in) | large-v3 | Slightly higher accuracy |
| Free (Alternative) | whipser.cpp (Win Built-in) | large-v3 | Faster, built into Windows |
| Free (Alternative) | Nemotron-3.5-asr-0.6b (Built-in) | - | Faster, built-in |
| Paid (Recommended) | OpenAI Speech Recognition API | — | Excellent results |
Chinese Videos
| Configuration Level | Channel | Model | Notes |
|---|---|---|---|
| Free (Recommended) | Qwen-ASR (Built-in) | 1.7B | Good Chinese results |
| Free (Alternative) | Alibaba FunASR (Built-in) | paraformer-zh | Good Chinese results |
| Free (Alternative) | Firered Chinese (Built-in) | Xiaohongshu Chinese & Dialects | Good Chinese results |
| Free (Alternative) | Huggingface_ASR (Built-in) | zai-org/GLM-ASR-Nano-2512 | Zhipu AI model, good Chinese results |
| Paid (Recommended) | Doubao Speech Recognition LLM Turbo | — | Good Chinese results |
| Paid (Recommended) | Xiaomi mimo-v2.5-asr | — | Good Chinese results |
| Paid (Alternative) | Ali Bailian ASR | — | Chinese-optimized |
Japanese Videos
| Configuration Level | Channel | Model | Notes |
|---|---|---|---|
| Free (Recommended) | openai-whisper (Built-in) | large-v3 | Good general results |
| Free (Recommended) | Nemotron-3.5-asr-0.6b (Built-in) | NVIDIA open-source multilingual model | Good results |
| Free (Alternative) | Huggingface_ASR | japanese-wav2vec2-large/Nemotron-3.5-asr-streaming-0.6b | Japanese-specific |
| Paid (Recommended) | OpenAI Speech Recognition API | — | Excellent results |
Minority Language Videos
| Configuration Level | Channel | Notes |
|---|---|---|
| Free (Recommended) | openai-whisper (Built-in) large-v3 | General model, supports dozens of languages |
| Free (Recommended) | Dophin (Built-in) | Specifically for Asian languages (select Auto Detect in the batch speech transcription interface) |
| Free (Recommended) | Omnilingual ASR (Built-in) | 1,600+ languages (select Auto Detect in the batch speech transcription interface) |
| Free (Recommended) | Huggingface_ASR (Built-in) | Various minority language models fine-tuned by the community on huggingface.co |
| Paid (Recommended) | Gemini LLM Recognition / OpenAI API | Good results for minority languages |
Further improve recognition quality:
- Explicitly specify the
Spokenlanguage for more accurate recognition - Check
Separate Vocal/BGMor checkDenoise - Check the
LLM Correctioncheckbox and select a top-tier AI channel and model underAdvanced Options -- LLM Provider for Proofreading - Consider LLM re-segmentation: Check
Menu - Tools - Advanced Options - Speech Recognition (ASR) -- Use LLM for Resegmentation Instead of Correctionto use LLM re-segmentation. The prompt file issoftware directory/videotrans/prompts/resegment/llm_re.txt. After checking this, do NOT embedBilingual Subtitles, because re-segmentation will inevitably cause the number of subtitle lines to mismatch the original subtitles.
Click to view usage instructions for each speech recognition channel
Step 2: Subtitle Translation
Goal: Translate the subtitles generated in Step 1 into the target language.
| Configuration Level | Channel | Notes |
|---|---|---|
| Preferred | DeepSeek / OpenAI ChatGPT / Gemini (latest models) | Best AI translation quality |
| Free | Google Translate / Microsoft Translate | Traditional translation, fast |
| Local | M2M100 | Fully offline translation |
| Local | Hy-MT2-1.8B | Tencent open-source translation model |
Key settings:
- Prefer AI channels such as deepseek / openai-chatgpt / Zhipu AI, etc., and use online flagship models such as
deepseek-flash, etc. - Check the
SendSRTcheckbox - If the model has a sufficiently large context and you don't mind multiplied token consumption, you can check
Advanced Options -- Subtitle Translation -- Include Full Transcript Context in AI Translation - If you want to further streamline the translation results to avoid excessively long dubbing, you can check
Advanced Options -- Subtitle Translation -- Further streamline translation - If you are able, you can optimize the prompts yourself. They are located in the
software directory/videotrans/prompts/srtfolder (you must checkSendSRT). Different channels correspond to different txt files; just open and edit them. Note that{xxx}are dynamic variables—do not delete or modify them. WhenSendSRTis unchecked, the prompts are located insoftware directory/videotrans/prompts/text. Hy-MT2 prompts are also in that folder.
Step 3: Dubbing
Goal: Generate dubbed audio based on the translated subtitles.
| Configuration Level | Channel | Notes |
|---|---|---|
| Free | Edge-TTS | Microsoft free interface, natural results, supports all languages |
| Local | Qwen-TTS, F5-TTS, OmniVoice, Confucius | Built-in, supports cloning |
| Paid | Doubao Voice 2.0 / Qwen-TTS (bailian) / Xiaomi / Minimaxi / OpenAI-TTS | High-quality commercial APIs |
| Clone | OmniVoice / Confucius / Qwen-TTS / GPT-SOVITS / CosyVoice / F5-TTS / Index-TTS / ChatterBox / ZipVoice / FireRed3-TTS | Use the original video's voice |
Click to view detailed information and usage instructions for dubbing channels
Step 4: Subtitle, Dubbing, and Video Sync Alignment
Goal: Synchronize subtitles, dubbing, and video. 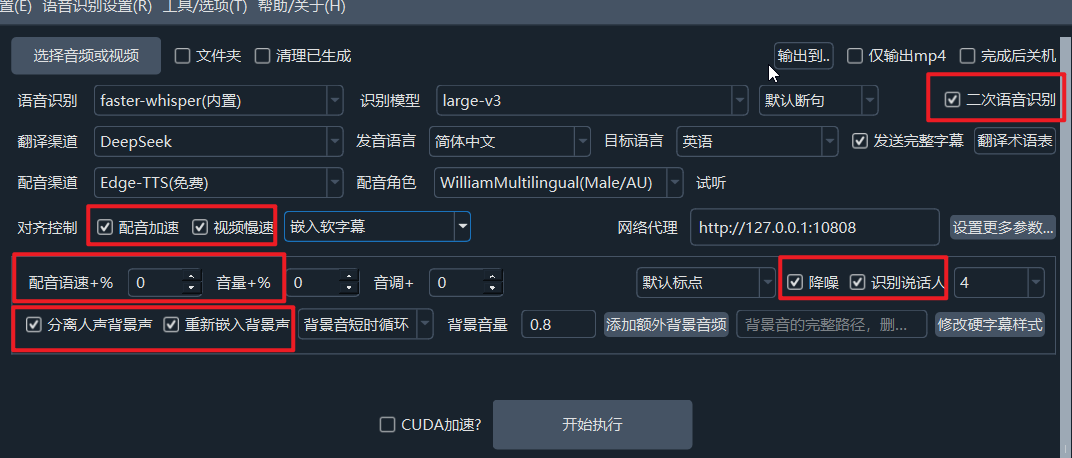
| Configuration | Notes |
|---|---|
| Check "Secondary STT" | After dubbing is complete, run speech recognition again on the dubbed audio to generate precise, short subtitles with accurate timelines |
| Set "Speed+%" | When translating Chinese to English, set +10 or +15 to speed up dubbing |
| Check "TTS Speedup" | Automatically speed up dubbing when it is longer than the original video |
| Also check "Slow Video" | Works best together with audio speedup |
| Remove In-between Silences | If neither TTS Speedup nor Slow Video is selected, this option will appear. When checked, silent segments between sounds will be removed so that sounds connect directly. If unchecked, any silence between original subtitles will be preserved. |
| Sync Subtitles & Speech | If neither TTS Speedup nor Slow Video is selected, this option will appear. Subtitles translated into other languages and then dubbed will most likely differ in duration from the original speech. When checked, subtitle timestamps will be forcibly modified so subtitles appear and disappear in sync with the audio |
| Check "Separate Vocal/BGM" | Embed the original background audio |
| Check "Denoise" | Improve original audio quality and recognition accuracy |
Menu - Tools -- Advanced Options - Dubbing Settings -- Trim Start/End Silence in Dubbed Segments: When checked, removes the silence buffer at the beginning and end of each dubbed segment, which helps with alignmentMenu - Tools -- Advanced Options - Dubbing Settings -- Strip All Silence in Dubbed Segments: When checked, removes all silence buffers, including at the beginning, end, and within sentences, which helps with alignmentMenu - Tools -- Advanced Options - Dubbing Settings -- Silence Removal Intensity: Selectinglowreduces removal intensity and removes fewer silent segments; selectingmaxincreases removal intensity and removes more silent segments
Step 5: Other Quality Improvements
Basic Settings
- Check
Separate Vocal/BGMor checkDenoise - Check
SendSRT, checkLLM Correction - Menu - Tools - Advanced Options - Subtitle Translation: Ensure the AI model used supports long context and long output
- Set
AI Translation Batch Size (Lines)to 100 or greater - Check
Use LLM for Resegmentation Instead of Correction. After checking, do NOT embedBilingual Subtitles, because re-segmentation will inevitably cause the number of subtitle lines to mismatch the original subtitles - Check
Include Full Transcript Context in AI Translation
- Set
When using clone roles to clone the original voice
- Set
Menu -> Tools -> Advanced Options -> Speech Recognition (ASR):- Min Speech Duration (ms): 3000
- Max Speech Duration (sec): 10
- Use an AI engine for the translation channel (DeepSeek / OpenAI ChatGPT), and check
SendSRT - Speech recognition: For Chinese,
Doubao STT Turbo / Qwen-ASR / FunASR / Firered Chineseis recommended; for English,Faster-whisper + large-v3is recommended, withDefault segmentchecked - If you need to re-embed background audio, click "More..." and check "Separate Vocal/BGM"; if not needed, check "Denoise"
FAQ
Q: What are the conditions for lossless video output?
The original video must be encoded as H.264 MP4 + "Slow Video" unchecked + no hard subtitles embedded + codec set to 264.
Q: Processing is very slow?
- Make sure GPU acceleration (CUDA) is enabled
- Use a smaller model
- Make sure the graphics card driver is up to date
Q: How do I use GPU acceleration?
Make sure the NVIDIA graphics card driver, CUDA 12.8, and cuDNN 9.11 are installed, then check "Enable CUDA?" in the main interface. AMD graphics cards do not support CUDA acceleration.
Related Documentation
- Improving AI Subtitle Translation Quality — Translation mode comparison and glossary usage
- Better Use of Local LLMs as Translation Channels — Local LLM configuration guide
- Modifying AI Translation Prompts — Customize translation prompts
- Recommended Best Settings for Video Translation — Optimal configuration for each stage
- Causes and Solutions for "Blank Subtitle Lines" After Translation