Comprehensive Guide - pyVideoTrans
This documentation applies to version
v4.17
Core Features: Video Translation / Speech-To-Text / Text-to-Speech / Translation Srt
- Video Translation: Translates video spoken in Language A into a video with Language B dubbing and Language B subtitles (Left panel: Translation V/A)
- Speech-To-Text / STT: Batch transcribes human speech from audio and video into timestamped SRT subtitle files (Left panel: Speech-To-Text)
- Voice Dubbing / Text-to-Speech: Uses local TTS models or cloud APIs to generate high-quality voiceovers from subtitles or text (Left panel: Text-to-Speech)
- Translate Subtitles: Batch translates SRT subtitle files while preserving timestamps and structure (Left panel: Translation Srt)

1. How the Software Works
The core workflow of Translation V/A takes a video in one language and outputs a new video with dubbing and subtitles in another language:
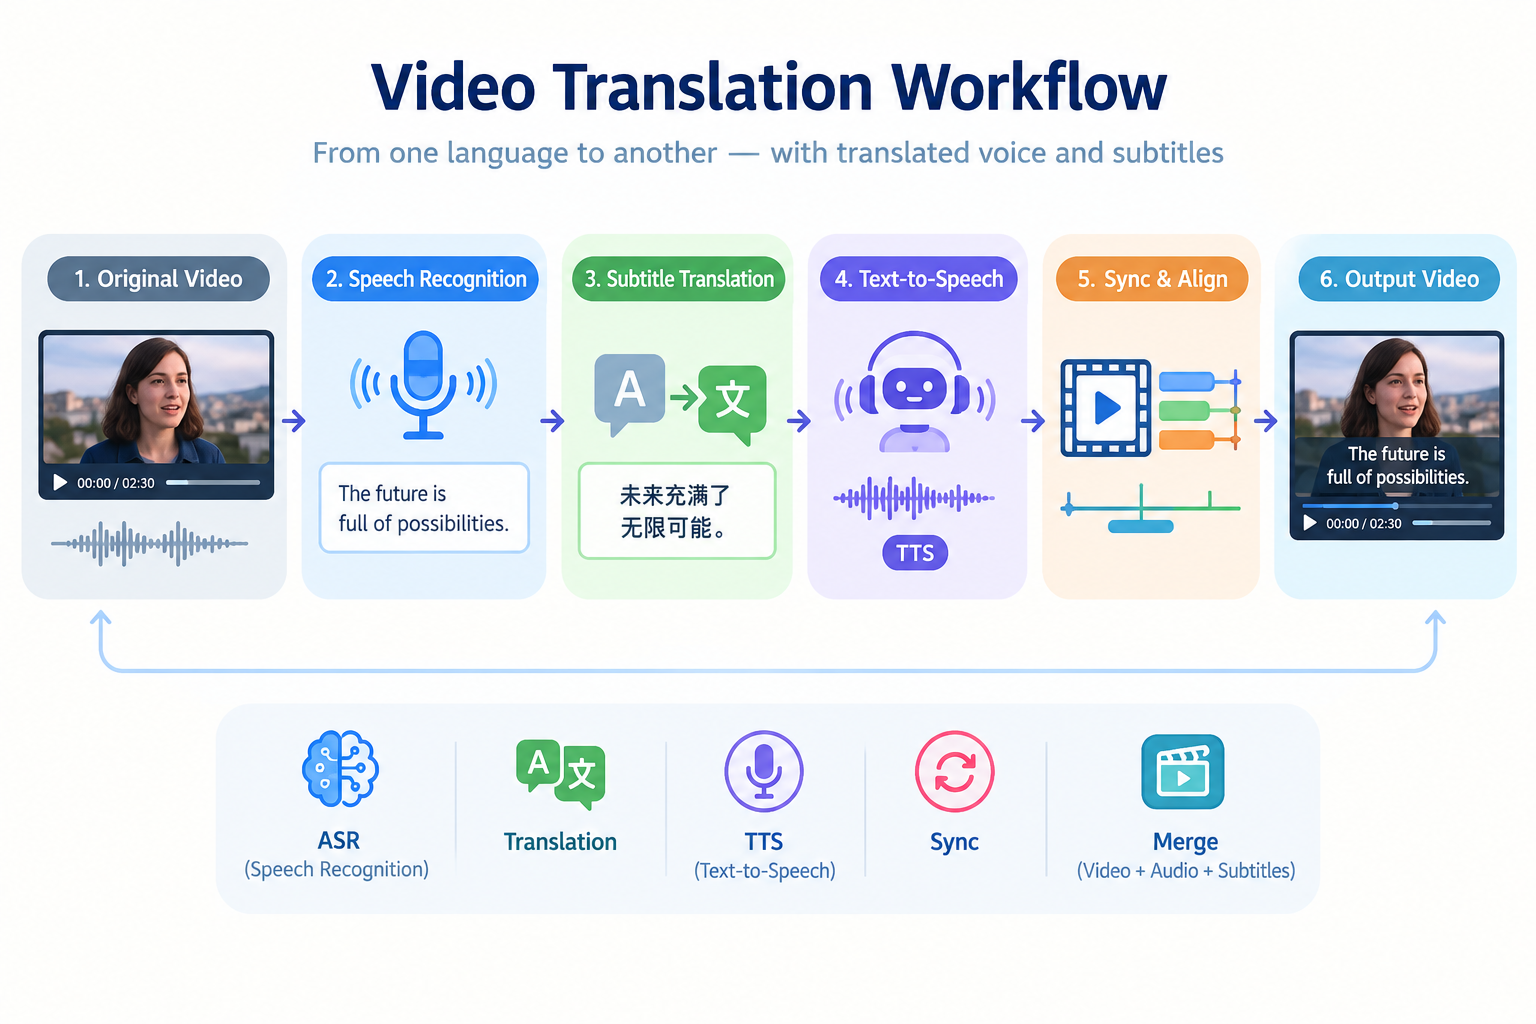
Plain English explanation:
- Speech-To-Text: Like a transcriber, it listens to the original video and writes out timestamped subtitles line by line.
- Subtitle Translation: Translates the transcribed subtitles into your target language.
- Voice Dubbing: Uses TTS engines to read the translated subtitles aloud in your chosen voice.
- Synchronization: Adjusts audio and video timing to align speech with on-screen action, burns in subtitles, and renders the final video.
The whole pipeline is automated—simply configure your settings and click start.
- Supported: Any video or audio file containing audible, intelligible human speech (whether it currently has subtitles or not).
- Not Supported: Videos containing only background music or silent visuals without spoken voice.
- Cannot Remove: Pre-existing burned-in hard subtitles cannot be erased by this software.
2. Download and Installation
Windows Users
- Download the pre-built package: Download Windows Package
- Extract it into a short folder path containing only English letters and numbers (e.g.,
D:\pyVideoTrans). - Double-click
sp.exeto launch. ⚠️ Do not attempt to runsp.exedirectly inside the ZIP archive.
💡 Beginner Tips & Must-Reads (Avoid 90% of Common Errors)
To ensure the software runs smoothly and to prevent common errors, please take 1 minute to check these key points before starting:
1. Where should you extract the software?
- ✅ Recommended location: Extract into a simple folder path, such as
D:/videotrans(the shorter the path, the better). - ❌ Never place it here: Do not extract into system-protected directories like
C:/Program FilesorC:/Windows(these folders have strict permission limits, which prevent the software from saving output videos and temporary files).
2. Disable security software or add the software folder to the trusted list
The software is packaged with Python and has no authentication or digital signature. Some security software may falsely report it as a virus or block it. Please add it to your trusted list in advance and run it with administrator privileges.
If you have security concerns, consider deploying from source code. View Source Deployment Guide
3. How should you name and store your video files? (Most common error cause!)
- ❌ Avoid long, complex names: Videos downloaded from YouTube, Bilibili, etc., often have extremely long file names containing emojis (e.g., 🔥, 👍, 🌟). Importing these files directly can easily cause system crashes or errors on Windows.
- ✅ Best practice: Before importing, rename the video to a short, simple name (such as
video1.mp4orinterview.mp4, removing all emojis and special symbols), and store it in a simple directory (such as your Desktop or the root of drive D:).
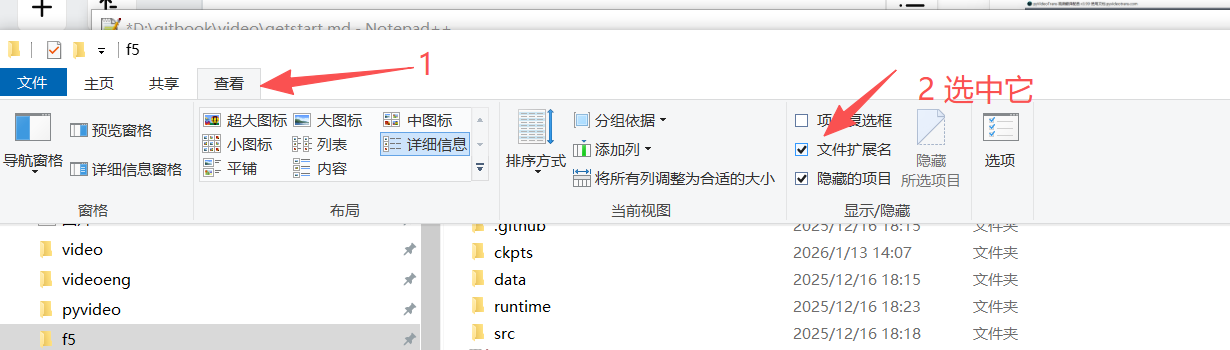
4. Recommended: Enable "File name extensions" (Avoid selecting wrong files)
Windows hides file extensions by default, making it hard to tell apart video, audio, or subtitle files—especially when they share the same name.
- How to enable: Open any folder, click View at the top ➔ check File name extensions (see image below).
macOS / Linux Installation Guide
Install system dependencies:
bash# macOS brew install libsndfile git brew tap homebrew-ffmpeg/ffmpeg brew install homebrew-ffmpeg/ffmpeg/ffmpeg # Ubuntu/Debian sudo apt-get install ffmpeg libsndfile1-devInstall
uv:bashcurl -LsSf https://astral.sh/uv/install.sh | shClone and run:
bashgit clone https://github.com/jianchang512/pyvideotrans.git cd pyvideotrans uv sync uv run sp.py
View Full Source Code Deployment Guide (macOS/Linux/Windows)
3. Interface Overview

From top to bottom, the main window is structured into these rows:
| Row | Function | Description |
|---|---|---|
| 1 | Select Video/Audio (Required) | Supports MP4/MKV/AVI/MOV/WAV/MP3, etc., with batch queue support |
| 2 | Speech Recognition | Choose STT engine and model to transcribe spoken dialogue into subtitles (Default: faster-whisper / large-v3-turbo) |
| 3 | Translation Subtitles | Choose translation provider, source language, and target language (Default: Google Translate) |
| 4 | Dubbing (TTS) | Choose TTS provider and voice character to speak the translated text (Default: Edge-TTS) |
| 5 | Synchronization | Auto Speedup, Slow Video, subtitle embedding, proxy settings (Default: Auto Speedup only) |
| 6 | Start Execution | Click to begin processing tasks |
| 7 | Progress Bar | Displays progress in real time; click to open the output folder; click when an error occurs to view detailed error information |
| 8 | More Settings | Access noise reduction, vocal/BGM separation, BGM re-embedding, and other advanced options |
| 9 | Subtitle Preview Area (right side) | Read-only area that displays recognized or translated subtitles in real time |
| 10 | Two subtitle import buttons at the bottom of the right panel | For single-video translation, you can Import Speech Language SRT or Import target language SRT to skip STT or translation |
What do Free, Local API, and Built-in mean?
- Free: Services like Google Translate, Microsoft Translate, and Edge-TTS run online for free out-of-the-box without registration. Be mindful that heavy, rapid requests may trigger rate limits.
- Built-in: Models that integrate directly into pyVideoTrans without requiring manual external setup, such as VITS/Piper/Qwen3-TTS/OmniVoice/F5-TTS/Qwen3-ASR/SuperionTTS/ChatterBox, etc. Note: To keep download sizes small, only the calling code is built-in; the models themselves are not included and will be downloaded on-demand when first selected.
- Local API: Open-source models running locally on your own machine. Once deployed and launched, enter their local API or WebUI URL in pyVideoTrans settings (e.g., GPT-SoVITS, CosyVoice).
4. Step-by-Step Video Translation Guide
Step 1: Select Video Files

Interface Elements:
Select Video/Audio: Click the button in the upper left corner to choose your media files. Supports MP4/MKV/AVI/MOV/WAV/MP3, etc. You can select one or multiple files. If only one video is selected, the software enters Single-Video Mode, where interactive editing pop-ups will appear allowing you to modify subtitles and re-dub segments on the fly.Folder: Check this to batch process all videos found inside a selected folder.Clear Output: Check this if you want to re-translate a video from scratch. When unchecked, the software reuses previously generated SRT transcriptions or translations to save time. If you are re-translating the same file and want to skip the time-consuming STT stage, leave this unchecked.Save To...: Click to specify a custom destination directory for the translated videos. If not specified, the default location is used.Output MP4 Only: When enabled, intermediate files (audio clips, SRT files) are cleaned up, leaving only the final translated MP4 file.Auto Shutdown: Automatically powers off your computer when all batch jobs finish. Suitable for large batches and long-running tasks.
Default Output Directory Behavior
When
Folderis unchecked: Files are saved to a_video_outfolder created alongside your source video. For example, if your file isD:/videos/001.mp4, the result is saved inD:/videos/_video_out/001-mp4/.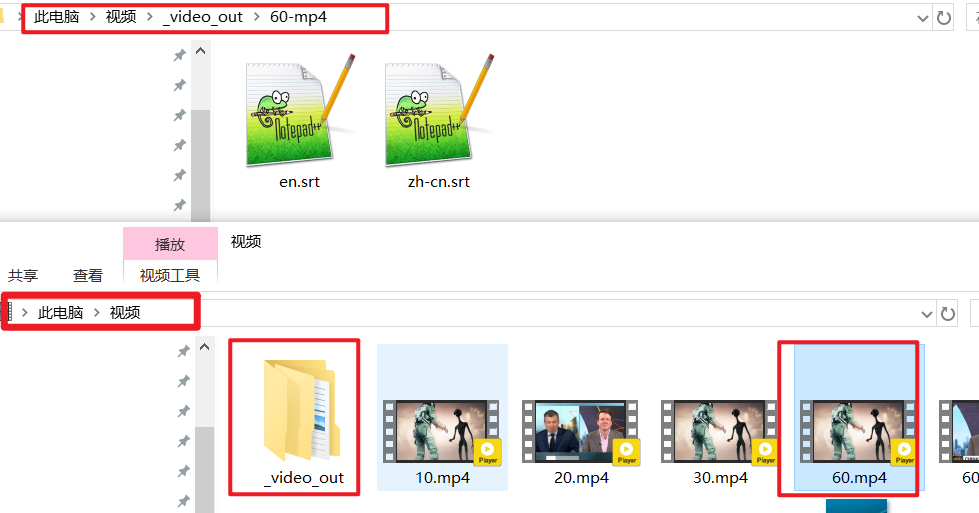
When
Folderis checked: Files are saved in_video_out/{FolderName}next to your folder. If your folder isD:/videos/test, output will be stored inD:/videos/_video_out/test/001-mp4/.Click the progress bar to automatically open the output folder.
If you specify a custom folder with Save To..., outputs will always go to your chosen location, not the default.
Step 2: Choose Speech Recognition Engine
This step transcribes spoken audio into text, directly determining the quality of subsequent translation and dubbing.

Interface Elements:
Speech Recognition:
| Service | Recommended Use | Notes |
|---|---|---|
faster-whisper (Local) | Default; tiny is fastest with lowest accuracy, large-v3 is most accurate but slowest | Fast |
openai-whisper (Local) | tiny is fastest with lowest accuracy, large-v3 is most accurate but slowest | Slightly higher accuracy, slightly slower |
Qwen-ASR (Local) | Chinese and ~15 other major languages | Excellent Chinese accuracy, slower |
Alibaba FunASR (Local) | Great for Chinese; offers paraformer/sensevoice/Fun-ASR-Nano models | Strong Chinese performance |
Nemotron-3.5-asr-0.6b (Local) | European languages plus Japanese, Korean, Vietnamese, etc. (40 languages) | Open-source model from NVIDIA |
Moss-Diarize (Local) | Chinese and ~15 other major languages | Supports speaker diarization for media under 90 minutes without a separate model |
Whisper.cpp (Win Built-in) | Built into Windows packages; needs manual setup on macOS/Linux | Lightweight C++ Whisper port |
FireRed Chinese (Local) | Chinese speech and regional dialects | Open-sourced by Xiaohongshu, runs on CPU |
Dolphin Asian (Local) | East Asian, Southeast Asian, and Middle Eastern languages | Dedicated to Asian languages, runs on CPU |
Omnilingual (Local) | Broad language coverage | Facebook open-source; wide coverage but moderate quality, runs on CPU |
Model: Different recognition channels display different models. For faster-whisper/openai-whisper channels, the available models are:tiny→ Fastest, lowest accuracybase/small→ Balanced choicemedium→ Better resultslarge-v3→ Best results, requires 8GB+ VRAMlarge-v3-turbo→ Recommended, balances speed and qualitytiny.en/base.en/small.en/medium.en/distil-large-v3/distil-large-v3.5→ English-optimized distilled models, only available when the spoken language is English
LLM Correction: Speech recognition inevitably produces typos, missing punctuation, and other errors. LLM Correction sends the recognition results to an AI LLM to fix typos and restore punctuation for smoother output. It defaults to theDeepSeekchannel and can be switched under Menu -> Tools/Options -> Advanced Options -> Speech Recognition (ASR) -> LLM Provider for Proofreading. The prompt file is stored at软件目录/videotrans/prompts/resegment/llm.txtfor custom adjustments.LLM Resegmentation: When
Menu -> Tools -> Advanced Options -> Speech Recognition (ASR) -> Use LLM for Resegmentation Instead of Correctionis checked, the LLM will re-segment sentences instead of just correcting errors. The prompt file isvideotrans/prompts/resegment/llm_re.txt. When checked, do not embed bilingual subtitles, as resegmentation will inevitably cause subtitle line counts to mismatch the original.SecondarySTT:
When a Voices role is selected and bilingual subtitles are not enabled, you can check SecondarySTT. After dubbing is finished, the software re-transcribes the newly synthesized speech to generate precise, compact subtitles tightly locked to the new voiceover.
In Advanced Options -> Speech Recognition (ASR) -> Secondary ASR Max/Min Speech Duration, setting smaller values helps generate shorter subtitles.
Note: SecondarySTT uses faster-whisper (defaulting to large-v3-turbo), which can be changed in this section.
Explicitly specify the Spoken language; use [Auto Detect] with care
Selecting the correct spoken language ensures significantly higher transcription accuracy.
Starting with v4.12, Auto Detect is available at the bottom of the Spoken dropdown for unknown sources. If you use Auto Detect:
- Only use
faster-whisper (Local),openai-whisper (Local), orQwen-ASR (Local). Other engines require a specified language. - When using
Google Translate (Free)orMicrosoft Translate (Free), mixed-language inputs (e.g., Simplified + Traditional Chinese) must have the source language explicitly selected; otherwise, the text will be returned untranslated. - Avoid bilingual subtitles when using auto-detection.
Adjust Subtitle Length and Segmentation (Fix Run-on or Broken Subtitles)
Different videos feature different speaking speeds, pause patterns, and background sounds. Direct recognition may produce fragmented subtitles (one word per line) or overly long subtitles (walls of text). You can customize segmentation rules to suit your video.
Default setting: Subtitle duration usually runs between 5–8 seconds, with a minimum duration of 3 seconds.
📍 Settings Location
Open the top menu: Tools / Options (&T) -> Advanced Options -> locate ASR Settings.
1. Core Parameter Breakdown
| Parameter | Unit & Default | Purpose |
|---|---|---|
| Max Speech Duration | Seconds (s) Default: 5 | The maximum target duration for a single subtitle line. Setting it to 5 aims for lines under 5 seconds. To avoid cutting off mid-word, a 1.5x buffer is applied (actual max: ~7.5–8s). 👉 Lower this value (e.g., 3–4) for shorter lines. |
| Min Speech Duration | Milliseconds (ms) Default: 3000(1000ms = 1s) | The minimum duration floor (prevents fragmented subtitles). Lines under this length merge into adjacent sentences. 👉 Lower this (e.g., 1000–1500) if you want short phrases like "OK" or "Thank you" on their own lines. |
| Min Silence Duration for Split | Milliseconds (ms) Default: 600 | Silence duration required to trigger a sentence break. A pause longer than 600ms ends the line and starts a new one. 👉 Raise this (800ms+) for longer, continuous sentences; lower this (200–400ms) for snappy, rapid cuts. |
2. Recommended Presets
🎬 Preset A: Short-form Video / Fast Commentary (Snappy & Punchy)
- Max Speech Duration:
2or3seconds - Min Speech Duration:
1000ms (1s) - Min Silence Duration for Split:
140ms - Result: Fast, concise subtitles suitable for TikTok, Reels, and fast-paced voiceovers.
- Max Speech Duration:
🎙️ Preset B: Lectures / Documentaries / Interviews (Complete & Structured)
- Max Speech Duration:
8or10seconds - Min Speech Duration:
3500ms (3.5s) - Min Silence Duration for Split:
800ms - Result: Complete, coherent sentences suitable for slower speaking rates.
- Max Speech Duration:
SecondarySTT Parameters (Dubbed Audio Only)
When SecondarySTT is checked, the software re-transcribes the freshly generated dubbing audio. Because synthesized speech is clear and consistent, tighter thresholds work well:
- Secondary ASR Max Speech Duration (s): Default
1.5. Recommended:1.0 ~ 2.0s for compact pacing. - Secondary ASR Min Speech Duration (ms): Default
600. Recommended:400 ~ 600ms to capture brief utterances.
Step 3: Choose Translation Service
Used to translate the STT-generated subtitles into the target language.

Interface Elements:
Translation Services:
| Service | Description |
|---|---|
| DeepSeek | High-quality LLM translation at very affordable pricing (Recommended) |
Google(Free) | Default; decent quality, requires proxy in restricted regions |
Microsoft(Free) | Free translation without proxy; subject to rate limits |
Hy-MT2 (Local) | Tencent Hunyuan 1.8B translation model |
M2M100 (Local) | Fully offline local translation |
Spoken: The language spoken in the videoTarget: The desired output languageSendSRT: When checked, AI channels receive the full SRT with timestamps rather than plain text, resulting in better translation quality.Glossary: When using AI translation channels, glossary entries are automatically added to the translation prompt. Click the glossary button and enter terms line by line in the format:Source Term=Target Term(e.g.,CEO=Chief Executive Officer).
Key Settings for Superior Translation Quality
- If blank lines appear in the translation results, it means the translation engine automatically merged adjacent subtitle texts. Setting both
Advanced Options -> Subtitle Translation -> AI Translation Batch Size (Lines)andTraditional Translation Batch Size (Lines)to 1 can improve this, but translation quality may decrease due to insufficient context. - When using AI translation, check
SendSRT— translations will be more natural. - When using AI translation channels, set
AI Translation Batch Size (Lines)to 100 or higher with a model that supports long context. - Check
Advanced Options -> Subtitle Translation -> Include Full Transcript Context in AI Translationto attach all original text as context for better quality (available from v4.12-0908). - When using AI translation, if the translated results are still too long after all other methods, causing dubbing duration to significantly exceed the original speech duration, check
Advanced Options -> Subtitle Translation -> Further streamline translation. This appends a prompt instruction requiring extremely concise translations. The prompt can be edited invideotrans/prompts/fragment/last_prompt.txt.
Step 4: Choose Dubbing (TTS) Service
This step generates speech for your translated subtitles.

Interface Elements:
TTS Service:
| Service | Description |
|---|---|
Edge-TTS(Free) | Recommended Default; Microsoft free API, natural voices, supports all built-in languages |
Qwen3-TTS (Local) | Alibaba local model; great quality but slow, supports voice cloning, 10+ languages |
| Audio.cpp(Local) | audio.cpp backend; supports switching between 10+ different TTS models |
F5-TTS (Local) | Supports Chinese, English, French, German, Italian, Japanese, Korean, Vietnamese, etc., with voice cloning |
| fish.audio | Online dubbing service; a good alternative to Elevenlabs.io, requires a fish.audio membership |
OmniVoice (Local) | Supports all built-in languages, supports voice cloning |
Confucius (Local) | Supports 14 languages including Chinese and English, supports voice cloning |
ChatterBox (Local) | Multilingual support (Chinese, English, etc.); strong European language performance, supports voice cloning |
ZipVoice ZH/EN (Local) | Chinese/English, supports voice cloning |
Moss-TTS-Nano (Local) | Multilingual (Chinese, English, etc.), supports voice cloning |
Higgs-audio-v3 (Local) | Multilingual (Chinese, English, etc.), supports voice cloning; CUDA acceleration requires 10GB+ VRAM, CPU requires 20GB+ RAM |
gTTS (Free) | Google TTS service; supports all built-in languages, requires proxy in restricted regions, average quality |
Voices: After selecting an engine, choose a voice actor from theVoicesdropdown (if no voices appear, select aTargetlanguage first). Non-clonevoices can be previewed by clicking theListenbutton.clonerole: Selectingcloneas the voice role means the original video's voice timbre will be cloned for dubbing. Make sureMin Speech Duration (ms)is set to at least 3000.Listen: If the selected voice supports preview, this button will appear.

Step 5: Audio, Subtitle, and Video Synchronization
Translating a sentence into another language inevitably changes its length, syllable count, and speaking duration—this is the root cause of audio/subtitle/video desynchronization after translation.
Use the following measures to adjust.

Interface Elements:
TTS Speedup: ✅ Enabled by default. Speeds up dubbed audio when it is longer than the original scene.Slow Video: ☐ Disabled by default. Slows down video footage when dubbing is longer than the original.Remove In-between Silences: ☐ Disabled by default. If neitherTTS SpeedupnorSlow Videois selected, this option appears. When checked, silent gaps between subtitle segments are removed, concatenating speech directly. When unchecked, original silent intervals between subtitles are preserved.Sync Subtitles & Speech: ☐ Enabled by default. If neitherTTS SpeedupnorSlow Videois selected, this option appears. Translated subtitles dubbed into another language will likely differ in duration from the original speech. Checking this forces subtitle timestamps to be modified so subtitles appear and disappear in sync with the dubbed audio.Subtitle Embedding Type: Defaults to soft subtitles. Subtitles are embedded into the video container (choose hard subtitles for web playback).Proxy: Some services (e.g., Google) are inaccessible in mainland China. If needed, enter a proxy address in the formathttp://127.0.0.1:7890. Ensure the proxy is running and the port is correct. If unsure, leave blank.
Improving Alignment Accuracy Open Menu -> Tools/Options -> Advanced Options -> Subtitle Dubbing:
- Remove start/end silence buffers from each dubbed segment: Removes silence at the start and end of dubbed audio to improve alignment.
- Remove all silence buffers from each dubbed segment: Removes all silence including start, end, and internal pauses to improve alignment.
- Silence removal intensity:
lowreduces removal strength (fewer silent segments removed);maxincreases removal strength (more silent segments removed). - When using AI translation channels, check
Advanced Options -> Subtitle Translation -> Further streamline translationto append an instruction for extreme conciseness. Edit the prompt atvideotrans/prompts/fragment/last_prompt.txt.
Subtitle Embedding Types:
- No Subtitles: Replaces audio only.
- Hard Subtitles: Subtitles are permanently burned into the video image, visible during web playback.
- Soft Subtitles: Default. Subtitles are saved as a toggleable stream inside the video container; not visible during web playback.
- Hard Subtitles (Bilingual): Displays source and target subtitles burned into the video simultaneously (disables SecondarySTT).
- Soft Subtitles (Bilingual): Toggleable bilingual subtitle track in media players (disables SecondarySTT).
Step 6: Start Execution

Import Speech Language SRT: If you already have the original SRT subtitles and don't want to re-run STT, click this button to import them. Only valid in Single-Video Mode.Import target language SRT: If you already have translated target-language SRT subtitles and don't want to re-translate, click this button to import them. Only valid in Single-Video Mode.Enable CUDA?: If you have an NVIDIA GPU with CUDA 12.8 and cuDNN 9 configured, check this to accelerate speech recognition several times over.Start Execution: Click to begin processing. The bottom progress bar displays real-time updates. Click it to open the output folder. When finished, the translated video is automatically saved to the output folder.
Single-Video Mode: If only one video is selected, 3-4 interactive editing pop-ups will appear during processing, allowing you to edit subtitles, re-dub, and preview the video. Learn more about Single-Video Mode.
5. More Settings (Improve Speech Recognition Quality)
For example: noise reduction, preserving background audio from the original video, speaker separation, speech speed adjustment, volume control, etc. Click More... to access these settings.

Click More... to expand:
| Setting | Description |
|---|---|
| Denoise | Removes background noise. Defaults to an ONNX model running on CPU; if you have an NVIDIA GPU, select the zipenhancer model under Advanced Options -> Denoise Model to use audio.cpp GPU acceleration |
| Default Punct / Restore Punct / Remove Punct | Remove Punct replaces all punctuation with spaces; Restore Punct attempts to reconstruct missing punctuation |
| Separate Vocal/BGM | Separates human speech from background music. Defaults to an ONNX model running on CPU; if you have an NVIDIA GPU, select mel_band_roformer under Advanced Options -> Vocal Separation Model to use audio.cpp and mel-band-roformer-q8_0.gguf on GPU |
| Re-embed BGM | Re-mixes original background audio back into the final video after dubbing |
| BGM Volume | Adjust background audio volume (0.0–2.0) |
| Extend/Loop BGM | How to handle when dubbing duration exceeds background audio duration: extend or loop the background audio |
| Speed+% | Adjust dubbing speed (-50% ~ +100%) |
| Volume+% | Adjust dubbing volume (-95% ~ +200%) |
| Pitch+ | Adjust dubbing pitch (-100Hz ~ +100Hz) |
| Identify Speakers | When checked, attempts to separate speakers in Single-Video Mode for use in the editing window. Select different models under Advanced Options -> Speech Recognition (ASR) -> Speaker Diarization Model |
| No Limit | Select the possible number of speakers. If the speaker count is known, selecting it improves accuracy |
| Subtitle Style | Opens the hard subtitle style editor |
6. Lossless Video Export
To export the final video without re-encoding the video stream (preserving 100% original picture quality), ensure all of the following:
- The source video is an MP4 file encoded in H.264.
- Slow Video is unchecked.
- Hard Subtitles are not embedded.
- Under
Menu -> Tools/Options -> Advanced Options -> Video Output Settings -> Video Codec (H.264 / H.265), select264.
7. Improving Translation Quality
Speech Recognition Channel Selection:- First choice: faster-whisper/openai-whisper with the
large-v3model. If VRAM is insufficient, uselarge-v3-turbo. - To further improve Chinese quality, choose
Qwen-ASR/Alibaba FunASR/ByteDance STT Turbo, etc. - For minor languages, use
openai-whisper+large-v3, orGeminiAI, or a specialized model for that language inHuggingface_ASR. - For Latin-script languages, besides
faster-whisper/openai-whisper, you can also trynemotron-stream-0.6b. - Check
LLM Correctionand select a top-tier AI channel and model underAdvanced Options -> LLM Provider for Proofreading. - Consider LLM Resegmentation: When
Menu -> Tools -> Advanced Options -> Speech Recognition (ASR) -> Use LLM for Resegmentation Instead of Correctionis checked, the LLM will re-segment sentences. The prompt file isvideotrans/prompts/resegment/llm_re.txt. When checked, do not embed bilingual subtitles, as resegmentation will inevitably cause subtitle line counts to mismatch the original.
- First choice: faster-whisper/openai-whisper with the
Subtitle Translation Channel Selection:- First choice: AI channels such as DeepSeek / OpenAI-ChatGPT / Zhipu AI, using online flagship models (e.g.,
deepseek-flash). - Check
SendSRT. - If the model's context window is large enough and you don't mind multiplied token consumption, check
Advanced Options -> Subtitle Translation -> Include Full Transcript Context in AI Translation. - To further streamline translation results and avoid excessive dubbing duration, check
Advanced Options -> Subtitle Translation -> Further streamline translation. - If capable, you can optimize the prompts yourself in
videotrans/prompts/srt(requiresSendSRTto be checked). Different channels correspond to different TXT files. Note that{xxx}are dynamic variables—do not delete or modify them. WhenSendSRTis unchecked, prompts are located invideotrans/prompts/text. Hy-MT2 prompts are also in that folder.
- First choice: AI channels such as DeepSeek / OpenAI-ChatGPT / Zhipu AI, using online flagship models (e.g.,
Dubbing Channel Selection:- Edge-TTS supports all built-in languages. For rare/minor languages, choose this.
- To improve Chinese dubbing quality, try Doubao Voice 2.0, Fish-audio, Index-TTS, Qwen-TTS, etc.
- To clone the original video's voice, use channels with a
clonevoice role, such asOmniVoice/Qwen-TTS/Audio.cpp/GPT-SoVITS/F5-TTS/Confucius, etc.
Synchronization:- First try selecting only
TTS Speedup(speeds up speech without changing video). - If unsatisfied, also select
Slow Video(slows down video). - If you don't want speech rate or video speed to change, uncheck both
TTS SpeedupandSlow Video, and useSync Subtitles & Speechwith or withoutRemove In-between Silencesto achieve alignment.
- First try selecting only
8. Advanced Options Reference
Access through Menu -> Tools/Options -> Advanced Options:

Click here for the complete guide to Advanced Options
9. Frequently Asked Questions (FAQ)
Why do different features support different numbers of languages?
Core reason: Supported languages depend entirely on the underlying model or API service you choose. Language coverage varies widely across tools:
- Speech Recognition (STT):
Whisperseries: Broadest coverage, supporting up to 99 global languages.Qwen-ASRand similar LLMs: Focus on high-quality recognition for around 15 mainstream languages.FireRed Chineseand specialized models: Tailored for single-language optimization (Chinese and regional dialects).
- Voice Dubbing (TTS):
Edge-TTS: Powered by Microsoft, supporting over 80 languages and dozens of regional accents.Qwen-TTS: Currently covers around 10 major languages.ZipVoiceand niche cloning models: Focus strictly on Chinese and English.
- Subtitle Translation:
DeepL,Tencent Translate, etc.: Traditional MT engines covering 10–30 common languages with high precision.Large Language Models (LLM): By understanding contextual meaning, LLMs support virtually any recognized human language.
⚠️ Important Notice: Language Selection Guidelines for Video Translation
The language dropdown currently contains about 80 languages. Please follow these rules:
1. Top 20–30 Common Languages (Chinese, English, Japanese, Korean, French, German, Spanish, etc.)
- Best Compatibility: Standard language codes are mapped across all translation providers.
- Recommended Services: Both traditional translation APIs (DeepL, Baidu, Tencent) and AI LLMs (OpenAI, DeepSeek, etc.) run stably.
2. Remaining 50+ Low-Resource / Rare Languages
- Strongly Recommended: Use only "AI Large Language Models" (such as DeepSeek, OpenAI, Gemini) as your translation channel!
- Why avoid traditional APIs for rare languages?
- Lack of provider support: Most traditional translation APIs do not support rare languages.
- Mismatched language codes: Different cloud providers use different ISO language codes for minor languages (e.g., one uses
fil, another usestl). The software does not map codes for all minor languages across all traditional providers; forcing them to run will likely cause immediate errors. - The AI advantage: LLMs understand natural language prompt names directly without relying on strict provider language codes, offering much higher reliability.
  "zh-cn": "Simplified Chinese",
  "zh-tw": "Traditional Chinese",
  "yue": "Cantonese",
  "en": "English",
  "fr": "French",
  "de": "German",
  "ja": "Japanese",
  "ko": "Korean",
  "ru": "Russian",
  "es": "Spanish",
  "th": "Thai",
  "it": "Italian",
  "pt": "Portuguese",
  "vi": "Vietnamese",
  "ar": "Arabic",
  "tr": "Turkish",
  "hi": "Hindi",
  "hu": "Hungarian",
  "uk": "Ukrainian",
  "id": "Indonesian",
  "ms": "Malay",
  "kk": "Kazakh",
  "cs": "Czech",
  "pl": "Polish",
  "nl": "Dutch",
  "sv": "Swedish",
  "he": "Hebrew",
  "bn": "Bengali",
  "fil": "Filipino",
  "bg": "Bulgarian",
  "my": "Burmese",
  "fi": "Finnish",
  "el": "Greek",
  "km": "Khmer",
  "lo": "Lao",
  "nb": "Norwegian (Bokmål)",
  "ro": "Romanian",
  "uz": "Uzbek",
  "pt-br": "Portuguese (Brazilian)",
  "es-419": "Spanish (Latin America)",
  "fa": "Persian",
  "ur": "Urdu",

# For the following languages, it is recommended to use AI channels only; other channels may not support them or may require mismatched language codes.

  "af": "Afrikaans",
  "sq": "Albanian",
  "am": "Amharic",
  "az": "Azerbaijani",
  "bs": "Bosnian",
  "ca": "Catalan",
  "hr": "Croatian",
  "da": "Danish",
  "et": "Estonian",
  "gl": "Galician",
  "ka": "Georgian",
  "gu": "Gujarati",
  "is": "Icelandic",
  "iu": "Inuktitut",
  "ga": "Irish",
  "jv": "Javanese",
  "kn": "Kannada",
  "lv": "Latvian",
  "lt": "Lithuanian",
  "mk": "Macedonian",
  "ml": "Malayalam",
  "mt": "Maltese",
  "mr": "Marathi",
  "mn": "Mongolian",
  "ne": "Nepali",
  "ps": "Pashto",
  "sr": "Serbian",
  "si": "Sinhala",
  "sk": "Slovak",
  "sl": "Slovenian",
  "so": "Somali",
  "su": "Sundanese",
  "sw": "Swahili",
  "ta": "Tamil",
  "te": "Telugu",
  "cy": "Welsh",
  "zu": "Zulu",
"ug": "Uyghur",💡 Quick Rule of Thumb for Beginners:
If translating major languages (Chinese, English, Japanese, Korean, etc.), any channel works fine.
If translating minor or rare languages, always choose an AI Model (like DeepSeek or ChatGPT) for the smoothest results.
Q: Can I run multiple instances of sp.exe at the same time?
Yes, but it is not recommended. Different instances share the same tmp folder; closing one instance will clear temporary files and likely crash tasks running in the other instance.
If you need parallel runs, copy the software folder to a new location (e.g., D:/aivideo and D:/aivideo2) and run each sp.exe independently.
Q: Why is processing running slowly?
- Check if GPU acceleration (CUDA) is enabled.
- Use smaller, faster models.
- Update your NVIDIA graphics card drivers.
Q: Why are transcription results inaccurate?
- Ensure the
Spokenlanguage matches the dialogue in the video. - Upgrade to a larger model.
- Enable
DenoiseorSeparate Vocal/BGMin More Settings. - Adjust the
VAD Speech Thresholdparameter.
Q: Why are subtitles, audio, and video out of sync?
This is normal. Different languages require different amounts of time to speak the same sentence. To fix alignment:
- Enable
TTS Speedup(enabled by default). - Also enable
Slow Video. - Increase
Speed+%to speed up the dubbing pace overall.
Q: Why is the exported video file size too large?
- Increase the
Video Quality Control (CRF)value (e.g., to 25–30). - Change the video encoder setting from 264 to 265.
- Disable
Slow Video.
Q: How do I enable GPU acceleration?
Verify your system has compatible NVIDIA drivers, CUDA 12.8, and cuDNN 9.11 installed, then check Enable CUDA? on the main window. AMD graphics cards do not support CUDA acceleration.
Q: What are the conditions for lossless video export?
Source video encoded as H.264 MP4 + Slow Video unchecked + no hard subtitles + codec set to 264.
Q: Can this software extract or remove hardcoded subtitles?
This software cannot extract or erase pre-existing hardcoded subtitles.
- To extract hard subtitles, use dedicated OCR tools such as Offline Hard Subtitle Extractor or video-subtitle-extractor.
- To erase hard subtitles from video frames, try open-source tools like video-subtitle-remover.
Q: What are some special tips and tricks?
- Create
netoffline.txtin the root directory to force offline model loading (will error if the model doesn't exist). - Create
no_resegment.txtin the root directory to disable faster-whisper/openai-whisper from re-segmenting based on word-level timestamps. Instead, sentence-level results from the model are used directly, which may not strictly follow the min/max subtitle duration settings. (Download the v4.15 patch and overwrite—even if you already have the full v4.15 package, you still need to apply the patch.) - Create
pyvideotrans_cpp.txtin the root directory to append additional parameters to the whisper.cpp command line. - Create
pyvideotrans.txtin the root directory to append additional parameters to the faster_xxl.exe command line. - Create
edgetts-noproxy.txtin the root directory to disable network proxy for Edge-TTS. - Create
crf.txtin the root directory to set the CRF value for video slow-motion segments. Default is 18; lower values increase clarity but slow processing and require more disk space. - Create
preset.txtin the root directory to set the preset value for video slow-motion segments. Choose from 'ultrafast', 'veryfast', 'medium', 'slow'. Default is veryfast. Moving right makes processing slower but produces slightly smaller files. - Create
huggingface.txtin the root directory to force model downloads from huggingface.co instead of domestic mirrors (though some models only available on modelscope.cn will still download from the source).
Related Documentation
- Improving AI Subtitle Translation Quality — Comparison of translation modes and glossary setup
- Best Practices for Local LLM Translation — Local LLM configuration guide
- Customizing AI Translation Prompts — Custom translation prompt instructions
- Recommended Best Settings for Video Translation — Optimal configurations for every stage
- Troubleshooting Blank Subtitle Lines